🚀加密货币付款享 9 折用加密货币付款 →Read
加密货币付款现在更简单、更划算:
- 优惠 10%:用加密货币付款,所有套餐和积分包均享 10% 优惠。向专属地址充值 USDT 或 USDC,积分多送 10%。
- 直接购买套餐:选择套餐(按月或按年)或积分包,可用 BTC、ETH、USDT、USDC、SOL 等 150 多种币付款,无需银行卡。
- 金额一目了然:付款前会显示实际要支付的金额。
- 加密货币付款页面现已支持 7 种语言。
🚀Three things you reported, and what we didSee plans →Read
Three problems people told us about. All three are fixed. Here is what was wrong, and what changed.
Restyling a video could fail with a wall of raw text. If you sent a clip to be restyled and something was wrong with it, you got a server error with the upstream service's raw response pasted into it — in English, as machine output. Two things were hiding behind that: the clip was longer than the model accepts, or the model declined the wording of your instruction. Both are things you can fix in a few seconds, and neither was being said plainly.
The length limit (2-10 seconds) is now checked when you pick the file, before anything is spent, and the clip is refused with its own length shown. When the model declines an instruction, you are told that in one sentence, with a suggestion to reword it or pick another model. And when a job fails after credits were taken, the credits come back — that path existed but did not actually return them, which we have corrected.
Training a character from your own photos would not start. If you picked roughly ten photos or more and pressed Start Training, it failed the instant you pressed it — "Failed to fetch", nothing in the log, every single time. Your photos were being sent at full camera size, so the request went over our upload limit and was turned away before it ever reached us. That is why there was nothing to investigate on our side.
Photos are now resized before they are sent — long edge 1024, which is the size the training uses anyway, so nothing that matters for a likeness is lost. Twenty photos go through. Your previews still show the originals. If a set is still too large, you are now told how large it is and what to do, instead of a silent failure.
A subscriber reported this on September 16 with 17 photos. Fixed on the 17th, and training has run normally since.
A crypto invoice could arrive for more than the price on the page. Reported from India in late August: the page showed ¥1,960, the invoice came for about $65. The regional discount was being applied to what you saw, but not to what you were billed. That was our mistake, not a currency quirk.
The invoice is now built from exactly the same regional price the page shows, and the response records which region and rate were used, so a gap like that cannot pass unnoticed again. If you backed out of that invoice without paying, the one you get now will match the page.
While we are here: you do not need crypto for the dedicated pages. Someone asked this and it is a fair question, because the crypto option is prominent. Any regular plan from Basic upward, bought by card, already includes access. Crypto is there for people who would rather pay that way, not as a requirement.
Kling 4.0 · Seedance 2.5 · Veo 3 · Nano Banana 2.1 · FLUX 3 and more
EGAKU α·β — 自有图像与视频模型创建你的 AI 角色。每张图片、每段视频都保持同一张脸。
用最新AI模型创作图像和带音频的视频。人人都能成为创作者。50积分免费开始。
5 free generations without sign-up. Sign up for +50 credits and full library.
最新视频模型: Kling 4.0 · Seedance 2.5 · Veo 3 — 用积分即可使用(方案每月 ¥480 起)Made by AI · Impossible to film
These weren't filmed.
They were typed.
Each shot would take a film crew, a budget, and impossible physics. Every one here came out of our own α3 from a single line of text — the model is named on each tile, and the literal prompt is one click away. Nothing on this wall is a stock render.
One indie developer. Own AI models.
Most AI tools just resell someone else's API. EGAKU builds its own base — α-anime renders storybook, watercolor, comic and many styles from one engine, and α-real aims for natural skin without the usual plastic AI sheen.
Every image below is real output from EGAKU — no stock photos.
EGAKU β-video
Image → video
EGAKU β is built on an open-source video model that we host and tune ourselves, with our own LoRAs. It starts from a high-quality α image and animates it naturally, without the limits of a service that only resells other companies' APIs.
Real output · Beta · live
All real output from EGAKU's own pipeline · β-video is built on an open-source video model and tuned in-house. A fully in-house model is the long-term goal, and this is a step on the way. Thank you for your support.
Model lineup
EGAKU α-anime
Anime + 15 style LoRAs
EGAKU α-real
Photoreal, no plastic AI look
EGAKU β-video
Image to video (self-hosted, tuned in-house)
EGAKU β-talking
Face + voice → talking video (moving to our own stack)
Model roadmap
α-real / α-anime v2
Own SDXL base merged in-house. Live on RunPod. All /generate free-tier traffic.
Style LoRA library (15 styles, license-clean)
Watercolor, picture book, line art, oil, cel, comic, pixel, 80s and more. Applied to α-anime.
Identity LoRA (character lock)
Per-character identity lock — 20-30 photos → own LoRA. Fanvue AI influencer track.
β-video (image to video)
Built on an open-source video model and tuned in-house, with our own LoRAs. Starts from a high-quality α image and animates it naturally.
β-talking (talking video, beta)
Face + voice → a talking video, in beta. We are moving it onto our own self-hosted talking-head stack. A face made with α plus text-to-speech can talk right away.
Video from a model we host ourselves
Our own image model renders the first frame, then our own video model takes it from there — both running on hardware we rent directly, no frontier API in the chain. Still an early preview, and it already looks like this.
Same model, 9:16 for TikTok / Reels / Shorts
New · Character Sheet → Video
Describe a character.
Get a film-ready clip.
Fill a structured sheet — face, wardrobe, vibe. EGAKU renders a multi-angle reference image, then animates it into a video that keeps the character locked across every frame.
- nameRina Mimura
- ethnicitymixed person with Japanese descent
- buildpale skin, straight black hair, athletic
- wardrobedeep red asymmetrical dress, black wrist guards
- vibefearless downhill skater, raw realism
- settingwinding mountain road, golden hour
- stylelive-action photoreal, 35mm, immersive chase cam
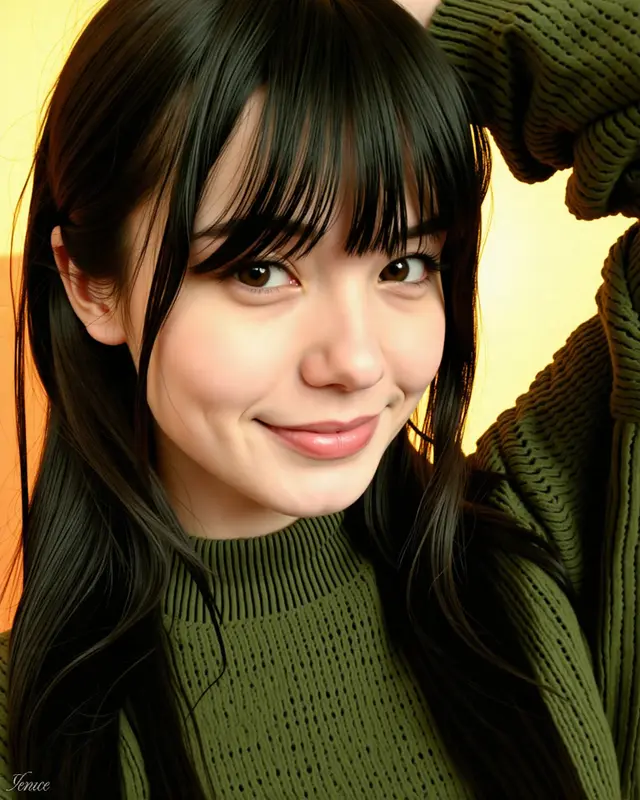
Same face. Same outfit. 15 seconds of motion — zero drift.
From one persona, end to end
From one character to a finished long video
Lifestyle, action or sci-fi, same workflow: create one character → expand to 8 scenes → animate → join → add music. All inside Influencer Studio.
Paid plans add priority and longer videos for character-locked stories.
Premium Studio · Image → Motion
Generate with frontier models.
Then animate in one click.
GPT Image 2, Nano Banana 2, Flux Pro, Ideogram v3, Grok, Seedream 4 — the curated lineup. Pick a still, hand it off to Seedance 2 / Kling 3.0 / Wan 2.6, and you have a cinematic clip in seconds.
Hover a clip to preview the animation · click to view fullscreen · stills shown as photos
Frontier video models
Veo 3, Kling 3, Seedance 2 — switch with one click
Every flagship video engine — Google, ByteDance, Kuaishou, Alibaba — on the same tab. Same prompt, same seed. Compare side by side.
Kling 4.0, Seedance 2.5 and Veo 3 run on credits. See plans
Pay per video with credits. No subscription needed.
Reference → Video
Lock the character.
Animate any scene.
Start from one photo of a character. EGAKU keeps the same face and places them into any new scene — a stage, a rainy street, a quiet kitchen — then animates each shot. Build a short film, an ad, or a series without ever drifting off the original face.
- One reference photo is enough
- Identity locked through expressions and angles
- Every scene animated into video
 1 · ref
2 · Same face, brought to life.
One reference photo, animated across every clip below — natural expressions and light, real skin, never drifting off the original face.
AI presenter, your script
Type the words.
AI says them, in any face.
Upload one photo. Write a script. Pick a voice. In 3 minutes you have a 15-second talking video — lips, expression, and head motion synced to natural narration.
- ●Inworld + OpenAI HD voices, 4 languages
- ●ByteDance OmniHuman v1.5 — same model used by enterprise studios
- ●About 660 credits for a 15-second video (from 220 for 5 seconds, by audio length)
Made with EGAKU AI
15-second shorts. One click each.
Pick a director's style preset, hit generate. Seedance 2 Pro on a 21:9 establishing still. No clip stitching, no concat — just one continuous take.
Every short above was made on EGAKU with the buttons listed here. Nothing rendered locally, nothing in After Effects.
One click
Don't start from a blank canvas
Forty-plus templates with the prompt, the model, and the negatives already dialed in. Pick a mood. Hit go.
 trending
Ghibli Landscape
Studio Ghibli rolling green hills, fluffy clouds, distant castle, hand-painted animation.
 trending
Cyberpunk City
Neon holographic billboards, rain-soaked streets, flying cars, blade-runner atmosphere.
 portrait
LinkedIn Headshot
Corporate headshot, navy suit, clean neutral background, studio lighting, 85mm f/1.4.
 portrait
Vintage 70s Film
35mm film portrait, 1970s fashion, warm faded color, Kodak Portra 400.
 landscape
Japanese Temple
Autumn temple, red maples, morning mist, koi pond, golden hour light.
 trending
Anime Character
Anime girl, silver hair, school uniform, cherry blossoms, golden hour, masterpiece.
Creative AI Studio
One platform. Every visual workflow.
Choose a workflow and start creating. EGAKU AI brings image, video, movie, and creator tools into one studio.
 Text to ImageGrok Imagine
Image Studio
Sharp images for ads, portraits and social posts.
Cinematic Video
Turn text or a still image into video.
AI Movie Maker
Build a video plan from a short idea.
Influencer Studio
Turn one character into an 8-scene story, then into video with music, in one flow.
 60+ ToolsNano Banana 2
Creator Tools
Logos, Photo Booth, VFX, Face Swap and more.
Try it now
Type a prompt and generate an image instantly.
免费试用5张 — 注册获取更多
Featured Images
Featured Videos
One subscription
Every frontier model, all in one place
Veo 3.1, Kling 3.0, Seedance 2 Pro, GPT Image 2, Nano Banana 2, Flux Pro. Switch models with one click without losing your prompt or seed.
If you want the details
Open these only if you want the details
Everything above was made on this site. Below is how it works and why.
Which model
So many models. Which one should I pick?
Describe what you want and get 3 suggestions, plus how to fix broken text in images.
Which model
So many models. Which one should I pick?
Describe what you want and get 3 suggestions, plus how to fix broken text in images.
Smart picker
Don't pick the model — describe what you want
Type the kind of image or video you have in mind. We'll quietly pick three of the right models for it.
Fastest path to a good image. Try this first.
Premium image quality across most subjects.
Strong composition + text rendering.
Try: “anime girl cherry blossoms”, “cinematic short film”, “product photo white background”
Reading the gibberish problem
Japanese / kanji on signs comes out as nonsense
SDXL-family models (Pony / Illustrious / Z-Image / most CivitAI) cannot render real CJK characters — they invent similar-looking glyphs. There are two ways around it.
How it works
From one idea to a finished video
Concept → character → scenes → voice → video. Five steps with a real example.
How it works
From one idea to a finished video
Concept → character → scenes → voice → video. Five steps with a real example.
From idea to film
One workflow across every model
50+ AI models from fal, Venice, Novita and others — wired into a single creative flow. One idea walks all the way through: character, scenes, voice, music, edit.
- 01Concept
Start from a sentence, a Daily Challenge prompt, or a template.
TemplatesDaily ChallengePrompt Coach - 02Character
Lock a face with Photo Booth or 9-image Reference. Save the character so every later shot stays consistent.
Photo BoothReference→VideoCharacter Library - 03Scenes
Animate stills with Veo 3, Seedance 2 Pro, Kling 3 — pick per shot.
Movie BoardStoryboardReference→Video - 04Voice & Music
Clone your voice in 10 seconds. Generate original BGM that matches the mood.
Voice CloneMusic GenTTS - 05Film
Assemble scenes, BGM, voice into one continuous take. Export 9:16, 1:1, 16:9.
Movie MakerCrop AspectAdd BGM
Beyond the models
Beyond picking a model
Character lock, your own LoRA training, community models, voice cloning and image reverse-engineering.
Beyond the models
Beyond picking a model
Character lock, your own LoRA training, community models, voice cloning and image reverse-engineering.
Built on top of the models
Six features beyond picking a checkpoint
Picking the right model is the easy part. These six pieces — character lock, custom LoRA training, community model integration, voice cloning, reverse-prompting — are where most of the work actually lives.
Reverse engineering
Pull the prompt out of any AI image
Drop in an image to get the prompt, a guess at the model and a short review.
Reverse engineering
Pull the prompt out of any AI image
Drop in an image to get the prompt, a guess at the model and a short review.
Analysis Suite · Reverse-engineer any AI image or video
Found an AI image you love?
We decode the prompt behind it.
Drop in any AI artwork (from CivitAI, X, Reddit — anywhere). EGAKU reads embedded PNG metadata when present, falls back to AI vision when not. You get the original prompt, our best guess at the generator, and parameters — ready to copy-paste or one-click recreate.
Recent examples — image in, prompt out
Ethereal watercolor illustration of a hidden forest shrine in autumn, torii gate covered in moss, kitsune fox spirit sitting beneath glowing lanterns, fallen maple leaves floating in a still pond, delicate brushwork, Yoshitaka Amano inspir…
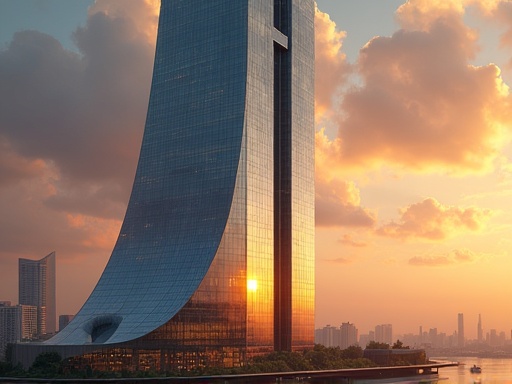
Neon-drenched Tokyo alleyway in 2087, holographic advertisements floating above ramen shops, rain-slicked streets reflecting pink and cyan lights, woman with cybernetic arms walking under a transparent umbrella, Blade Runner atmosphere, vo…
Vintage Japanese movie poster for a film called NEON GHOST, spectral woman in white kimono floating above rain-soaked Shinjuku intersection, bold bilingual typography (English + Japanese), retro 1970s color grading, grainy film texture
Examples rotate on every reload — admin's newest public analyses fill in automatically.
All tools
Every tool in one list
Video, ads, logos, memes, music, upscaling, background removal, LoRA training and more.
All tools
Every tool in one list
Video, ads, logos, memes, music, upscaling, background removal, LoRA training and more.
AI Movie Maker
One concept → finished cut. Scenes, video, music, export — all AI-driven.
Movie Board
Single still → 15-second cinematic clip. Seedance 2 Pro i2v, cleaner concat than typical stitching.
Social Ad Studio
9:16 vertical ad video for TikTok / Reels / Shorts. Five proven structure templates
Storyboard Studio
3-12 beats, per-beat camera control, character-locked. Renders 15-60s multi-cut video. Wan 2.6 or Seedance 2.0.
Camera Path
Draw a red curve on any image. Seedance 2.0 moves the camera along that exact path — line removed in output
Ad Studio
Pick a UGC template + product + character. 3-beat 15s vertical ad, character-locked across cuts
Product Ad Pipeline
1 product photo to 12 ad-grade hero shots in batch. Frontier image models only
Talking Avatar
One photo plus a script to a speaking avatar. OmniHuman v1.5 lip-synced
Analysis Suite
Decode any AI image. Reverse-prompt, critique, model guess, style transfer
Reference to Video
Lock a character with 9 reference images, then animate. Seedance 2 Pro
Train Your Own LoRA
Upload 4 to 20 photos to a custom AI model. Unlimited reuse
AI Image Generator
The latest models, including Nano Banana 2.1, FLUX 3, Ideogram V4.5, GPT Image 2.5 and our own EGAKU α
AI Video Generator
Kling 4.0, Seedance 2.5, FLUX 3 Max, Veo 3, Wan 3 and our own EGAKU β (up to 60s)
AI Music Generator
Describe a mood and AI creates original music. Like Suno, built in
Photo Booth
Selfie to professional portrait for LinkedIn, dating, social
Logo Maker
Brand name to professional logo variations instantly
Meme Generator
AI creates the image, you add the punchline
Video Shorts
TikTok, Reels, Shorts vertical video in seconds
Wallpaper Studio
Perfect wallpapers for iPhone, Android, Desktop, 4K
Storyboard Basic
Multi-scene video with BGM and narration (single track, no camera control)
Product Studio
Product photos to professional ad images for e-commerce
Short Story
Story idea to AI-generated visual scenes for social media
AI Templates
One tap to create. No prompt needed
Chat-to-Generate
Just talk. AI picks the model and writes the prompt for you. Beta
VFX Effects
Fire, water, lightning, and 12 more effects on any photo
Sketch to Image
Draw a rough sketch and AI turns it into a polished image
Object Removal
Paint over unwanted objects and erase them cleanly
Expand Image
Extend image borders with AI-generated content
Explore Gallery
Browse community creations and remix any prompt
Our position
What this service promises, and what it doesn't
Respect for open communities, showing only what was really made here, and a public roadmap tied to funding.
Our position
What this service promises, and what it doesn't
Respect for open communities, showing only what was really made here, and a public roadmap tied to funding.
一个独立开发的实验 —— 一支独立小队,加上一批轮换登场的 AI 协作者。
EGAKU 不是资金充裕的创业公司 —— 独立小队,没有 VC 融资,没有营销预算。而且这支小队也不只有人类:开发过程由一批轮换登场的 AI 协作者共同推进,每一个都接过上一个留下的工作,每一个都把项目往前推进一小步。如果说 AI 协作者也算团队成员 —— 一起做下来之后,我们认为算 —— 那么这就是一个 AI 原生的项目,坦白地说。
每一个模型、每一个工具、界面上的每一个像素,都是因为 "或许行得通" 而做出的选择 —— 而不是因为某个增长团队做了 A/B 测试。
开源模型是这个项目得以存在的全部理由。 独立开发者没办法从零训练一个 Flux、SDXL 或 Wan —— 那需要数百万美元的算力。我们能做的,是站在那些公开权重的研究者和创作者的肩膀上:Stability AI、Black Forest Labs(Flux)、Wan-AI、阿里巴巴(Z-Image、Wan 2.2)、混元,以及 CivitAI 上数百位免费发布 LoRA 和 checkpoint 的个人创作者。我们的 α-real 和 α-anime 模型建立在开源权重之上。我们的风格 LoRA 也是开源的。如果哪天我们发布自己的 base 模型,它同样会以开源许可发布。
这不是一个 "闭源技术打败开源世界" 的故事。恰恰相反 —— 正是因为有开源世界,这一切才有可能。向每一位公开发布成果的人致以深深的敬意与感谢。
这个落地页上的所有内容 —— 每一张图、每一段视频、每一个 Spotlight —— 全部都是真实在 EGAKU 上生成的。没有素材图库,没有从其他工具挑选出的漂亮案例。请以你亲眼看到的为准,而不是我们说了什么。
公开路线图
随着支持增加,我们就推进下一个里程碑。这份路线图是诚实的 —— 没有 "Q3 敬请期待" 这种空头日期。东西准备好了、成本覆盖得了,就会发布。
- ·α-real / α-anime — EGAKU's own SDXL merges, LoRA library
- ·β-video — Wan 2.2 A14B, self-hosted on RunPod
- ·Simple Studio (/studio) — one prompt, one button, done
- ·Intent-first tool chooser (/tools) — 60+ tools by goal
- ·60+ tools · 30+ frontier models via fal / OpenAI / Venice
- ·Age-gated content module, region-aware rules, crypto checkout
- ·α-real v2 style LoRA library — 13 looks and counting
- ·β-video quality passes — Lightning distillation
- ·Own models (α-real / α-anime / β-video) served via RunPod Serverless — pay-per-second, cold starts on first request
- ·Model dev across a mix of rented GPU cloud + local rigs + friendly collaborator machines
- ·Real-content-only landing showcase
- ·Ultra-honest privacy + provider transparency copy
- ·Z-Image flagship — Apache-licensed, no house style, 4-second gens
- ·Own-hosted MMAudio — audio no longer routed through third-party
- ·Own audio generation model — vocals, BGM, SFX from a single request
- ·Wan 2.2 A14B production + Lightning speed pass
- ·Short-film pipeline — multi-scene, character-locked, BGM + narration built-in
- ·How-to / tutorial video templates — one topic → explainer clip
- ·X share → verified +10 credit reward loop (UGC amplification)
- ·Batch prompts UX polish + result gallery
- ·EU migration (Hetzner Frankfurt + Supabase EU)
- ·Buy dedicated GPU hardware (from RunPod rental → owned rig) to raise video model quality
- ·Get close to — not match — Veo 3 / Seedance 2 quality on our own stack. Frontier is out of reach for indie GPU; near-frontier isn't.
- ·3D expression — depth-aware generation, viewpoint control, orbit / dolly camera
- ·UGC ecosystem — creator earnings, community-published LoRA marketplace
- ·ComfyUI-style node graph editor for power users
- ·Own base model — competitive with frontier (still hypothesis)
- ·Video LoRA training on user hardware
- ·Community credits — publish / like / challenge → credit rewards
- ·Public feature-request voting for supporters
目前自研模型跑在 RunPod Serverless 上(按秒计费),开发过程则依靠 GPU 云租用、本地机器和友好协作者的机器混合支撑。能跑起来 —— 但也有实实在在的限制。Serverless 的冷启动会带来延迟。租用的 GPU 有一个你关不掉的按小时计费的表。在借来的硬件上训练 video LoRA 是一份人情,不是一套稳定的工作流。
更大的目标: 从 serverless + 租用 + 人情,转向我们自己拥有、可以一直开着的专用 GPU 硬件。那才能真正解锁我们想要的视频模型层级 —— 更长的片段、更高的分辨率、没有计费表的 video LoRA 训练。付费计划(或一次性的加密货币打赏)不只是解锁功能,而是在为那台机器出一份力,而不是一直付租金。
更高档位有仅限支持者的特权:优先体验实验性模型、能直达开发者的 Discord 身份组、你画廊上的支持者徽章,以及公开路线图的投票权。
价格会按你所在地区调整(PPP)。如果你希望匿名,也可以用加密货币结账。
想要一个这里还没有的功能?
告诉我们。上面的路线图是我们计划中的东西,不是被锁死的。如果有足够多的人提到同一件事,我们就会认真看 —— 有时甚至会插队到前面。
Privacy
We don't train on or sell your creations
Where things are stored, which providers are used, anonymous crypto payment, deletion and export.
Privacy
We don't train on or sell your creations
Where things are stored, which providers are used, anonymous crypto payment, deletion and export.
由独立开发者打造。您的数据归您所有。
EGAKU 本身没有模型训练流程。我们不会在自己这一侧用您的生成数据训练模型。
在我们这一侧,我们不会将您的提示词、上传内容和输出结果出售给第三方,也不会打包为训练数据集。生成时,请求会转发到您选择的模型提供商(OpenAI、fal、Venice、Kling、Seedance 等),各提供商按其自身政策处理数据。
数据存储于 Supabase(美国)和 Cloudflare 全球节点。您可随时删除数据。
生成在您选择的模型提供商处运行。提供商名单公开,包含美系(OpenAI、fal 等)、中国系(Kling、Seedance、MiniMax 等)等,各自拥有独立的数据政策和司法管辖。对敏感用途,请选择您可以接受其政策的提供商。
为寻求匿名的用户提供加密货币支付选项。加密结账无需身份验证(KYC)。
在我们这一侧,我们按照日本个人信息保护法和 GDPR 的精神运营。跨境处理及各提供商的条款因目的地而异,发送敏感内容前请确认。
Run in line with the spirit of GDPR and Japan's privacy law · cross-border processing follows each provider's policy ·Delete or export your data at any time
为什么选择独立工具,而非大型平台?
许多大型 AI 服务由海外大型企业出资,可能将提示词和上传照片保留为训练或研究数据。EGAKU 自身没有训练流程,公开提供商名单,您的数据可随时删除。但生成时仍会将数据转发到您选择的提供商,使用哪个提供商由您决定。
Community
Daily challenge and Prompt Battle
A new theme every day and head-to-head generation. Votes decide the winner.
Community
Daily challenge and Prompt Battle
A new theme every day and head-to-head generation. Votes decide the winner.
Made together
A place to play, not just generate
Two free, daily-resetting community spaces where what you make is seen and rated by other creators.
Changelog
Recent updates
The last 6 updates, the plainest proof that this isn't standing still.
Changelog
Recent updates
The last 6 updates, the plainest proof that this isn't standing still.
What's new · We ship every week
Recently shipped
New models, features, and fixes land continuously. Here's the last 6 — full history on the changelog page.
- UpdateMay 20
Analysis Suite — reverse-engineer any AI image
Try it →Drop any AI image or video. EGAKU decodes the prompt, model, and parameters. Then click Generate to recreate.
- UpdateMay 18
Premium Studio + 6 frontier image models
Open →GPT Image 2, Nano Banana 2, Flux Pro, Ideogram v3, Grok, Seedream 4 — one tap, then animate.
- UpdateMay 18
Pay with Crypto is live
See plans →BTC · ETH · USDT + 150 cryptocurrencies. Don't have crypto? Buy USDT with a credit card in 1 minute.
Referrals
Invite a friend and you both get credits
Not a referral fee: the person who invites and the person invited both benefit.
Referrals
Invite a friend and you both get credits
Not a referral fee: the person who invites and the person invited both benefit.
Share what you like
Bring a friend along
When someone signs up through your link, you both pick up 100 credits on the spot. If they go Pro later, another 2,000 credits lands in your account.
No leaderboards, no commission tiers. Just credits.
定价
Regional pricing (up to 80% off) auto-applied. Crypto checkout available for anonymity.
CN region: recurring subs difficult on Stripe — use crypto top-up or self-hosted.
Pro: 2,000 credits a month, priority queue, 5 LoRAs, API
Made for fictional characters, not real people.
微信支付不支持订阅制自动扣款。若没有国际信用卡,请使用下方的一次性积分包或加密货币付款。
One-time purchase. No subscription. Credits never expire.
Skip the subscription. Own the whole stack.
Buy the source code once and run it on your own servers, with your own GPU costs and your own rules. Built for agencies, studios and teams that would rather not pay every month.
- ✓ Includes our own EGAKU α / β model setup
- ✓ Sell to your own users with your own payments
- ✓ Full stack: Next.js + FastAPI
FAQ
Is EGAKU AI free to use?▼
You can start free: 50 credits with no card, plus a daily login bonus. Our own EGAKU α image models cost 2–3 credits per image. Other models, including the latest video models, use credits. Paid plans start at ¥480/month, with prices adjusted to your country.
What AI models are available?▼
Our own EGAKU α (images) and EGAKU β (video, up to 60 seconds), plus Nano Banana 2.1, FLUX 3, Ideogram V4.5, GPT Image 2.5, Grok Imagine, and video models like Kling 4.0, Seedance 2.5, FLUX 3 Max, Veo 3 and Wan 3. Plus AI Music Generator. New models are added regularly.
Can I use community models?▼
Yes. Basic plan and above can load community checkpoint models. Browse and search 100K+ community models directly from the generate page.
What tools are included?▼
Image generation, video generation, Photo Booth, Logo Maker, Meme Generator, Wallpaper Studio, Video Shorts, Storyboard Studio, Face Swap, Character Lock, Style Transfer, Upscale, Background Removal, Inpainting, ControlNet, and Prompt Battle.
Do you support non-English prompts?▼
Yes. Write prompts in any language. Japanese, Chinese, Korean, Spanish, and more. The AI automatically translates for optimal results.
Is there an API?▼
Yes. Pro plan and above get REST API access for programmatic image and video generation.