🚀암호화폐 결제 10% 할인암호화폐로 결제 →Read
암호화폐 결제를 더 쉽고 저렴하게 바꿨습니다.
- 10% 할인: 암호화폐로 결제하면 모든 플랜과 크레딧 팩이 10% 할인됩니다. 고정 주소로 USDT·USDC를 입금하면 크레딧이 10% 더 들어옵니다.
- 플랜 바로 구매: 플랜(월간·연간)이나 크레딧 팩을 고르고 BTC·ETH·USDT·USDC·SOL 등 150종 이상의 코인으로 결제할 수 있습니다. 카드가 필요 없습니다.
- 금액을 미리 확인: 결제 전에 실제로 낼 금액을 보여 줍니다.
- 암호화폐 결제 페이지가 7개 언어를 지원합니다.
🚀자체 영상 모델, 기다리기 편해졌습니다예시 보기 →Read
자체 영상 모델을 기다리는 동안의 불편을 줄였습니다.
- 자동 재시도: 생성 도중 실패하면 추가 크레딧 없이 한 번 자동으로 다시 시도합니다. 두 번째도 실패하면 크레딧을 돌려드립니다.
- 진행 상황 표시: 대기 중인지 생성 중인지, 경과 시간과 남은 시간의 대략적인 예상을 보여 줍니다.
- 완성 알림: 영상이 완성되면 알림을 받을 수 있습니다. 다른 탭으로 옮기거나 페이지를 닫아도 괜찮습니다(완성된 영상은 My Gallery에 들어갑니다).
- 홈 화면에 새 예시: 오픈소스 영상 모델을 바탕으로 직접 조정한 자체 영상 모델로 만든 예시입니다. 페이지를 열 때마다 다른 영상이 나옵니다.
🚀이용약관 업데이트: 타사 모델 조건약관 보기 →Read
일부 영상 옵션은 다른 회사가 각자의 라이선스로 제공하는 AI 모델로 작동합니다. 이 모델들에 붙는 추가 조건(예: 결과물을 다른 AI 모델 학습에 쓰지 않을 것, 필요한 경우 AI가 만든 것임을 표시할 것)을 설명하는 항목을 이용약관에 추가했습니다. 평소 EGAKU를 쓰는 방식은 달라지지 않습니다.
Veo 3 · Grok · Flux · Kling 3.0 · Seedance 2.0 + 30 Models
EGAKU α (our own model) — now in betaVeo 3 · Grok · Flux · Kling 3.0 · Sora 2 + 30 모델
멋진 이미지와 시네마틱 비디오를 오디오와 함께 만드세요 — 누구나 크리에이터가 될 수 있습니다. 30개 이상의 AI 모델, 얼굴 교체, 포토 부스, 비디오 쇼츠, 스토리보드 스튜디오. 시작 시 50 무료 크레딧 제공.
5 free generations without sign-up. Sign up for +50 credits and full library.
유료 플랜에서 사용 가능 Veo 3 · Kling 3.0 · Seedance 2 Pro (월 ¥980부터)Made by AI · Impossible to film
These weren't filmed.
They were typed.
Each shot would take a film crew, a budget, and impossible physics. Every one here came out of our own α3 from a single line of text — the model is named on each tile, and the literal prompt is one click away. Nothing on this wall is a stock render.
One indie developer. Own AI models.
Most AI tools just resell someone else's API. EGAKU builds its own base — α-anime renders storybook, watercolor, comic and many styles from one engine, and α-real aims for natural skin without the usual plastic AI sheen.
Every image below is real output from EGAKU — no stock photos.
EGAKU β-video
画像 → 動画
Wan 2.2 A14B を自社ホストし、自社 LoRA + ComfyUI ワークフローで構築した EGAKU β。α / Z-Image の高品質画像を起点に、表現を絞り込まず自然に動かす統合フロー。フロンティア API を束ねる競合には構造的にできない領域です。
Real output · Beta · live
すべて EGAKU 自社パイプラインの実出力 · β-video は Wan 2.2 A14B をベースに自社 LoRA + ComfyUI で構築。 完全 in-house モデルを長期目標に、その途中段階として提供しています — 応援よろしくお願いします。
Model lineup
EGAKU α-anime
Anime + 15 style LoRAs
EGAKU α-real
Photoreal, no plastic AI look
EGAKU β-video
画像→動画 (Wan 2.2 A14B 自社ホスト)
EGAKU β-talking
顔+音声→喋る動画(自社ホスト talking-head 統合中)
Model roadmap
α-real / α-anime v2
Own SDXL base merged in-house. Live on RunPod. All /generate free-tier traffic.
Style LoRA library (15 種・license-clean)
水彩 / 絵本 / ラインアート / 油彩 / セル / コミック / ピクセル / 80s 等。α-anime に適用。
Identity LoRA (Fanvue キャラ)
Per-character identity lock — 20-30 photos → own LoRA. Fanvue AI influencer track.
β-video(画像→動画)
Wan 2.2 A14B 自社ホスト + 自社 LoRA + ComfyUI。α/Z-Image の高品質画像を起点に I2V で動かす統合フロー。表現の自由度とカスタム LoRA が差別化(API 束ねには不可能)。
β-talking(喋る動画・ベータ公開)
顔 + 音声 → 喋る動画をベータ公開。自社ホスト talking-head(InfiniteTalk on Wan2.1・Apache・WanVideoWrapper)を統合中で、順次この基盤へ載せ替え。α で作った顔 + TTS からそのまま喋らせられる。
Video from a model we host ourselves
Our own image model renders the first frame, then our own video model takes it from there — both running on hardware we rent directly, no frontier API in the chain. Still an early preview, and it already looks like this.
Same model, 9:16 for TikTok / Reels / Shorts
月41セッションが宣伝ゼロで来てる本命ルート
New · Character Sheet → Video
Describe a character.
Get a film-ready clip.
Fill a structured sheet — face, wardrobe, vibe. EGAKU renders a multi-angle reference image, then animates it into a video that keeps the character locked across every frame.
- nameRina Mimura
- ethnicitymixed person with Japanese descent
- buildpale skin, straight black hair, athletic
- wardrobedeep red asymmetrical dress, black wrist guards
- vibefearless downhill skater, raw realism
- settingwinding mountain road, golden hour
- stylelive-action photoreal, 35mm, immersive chase cam
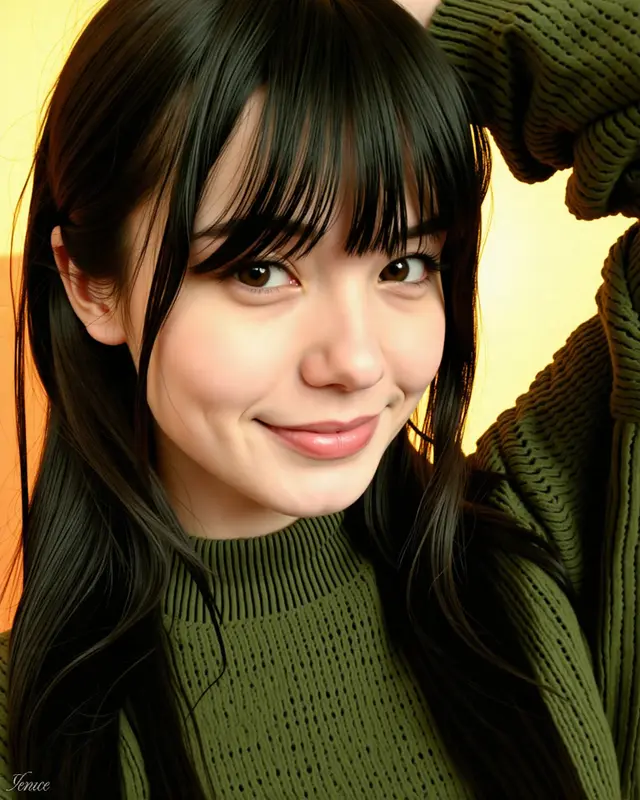
Same face. Same outfit. 15 seconds of motion — zero drift.
From one persona, end to end
1 人のキャラから、 完成形の長尺動画まで
同じワークフローで lifestyle / action / SF まで。 1 キャラを生成 → 8 シーンに展開 → 動画化 → 連結 → 音楽合わせ。 全部 Influencer Studio 内で完結。
キャラ固定 + 長尺は有料プランで本領発揮(優先 + より長い動画)
Premium Studio · Image → Motion
Generate with frontier models.
Then animate in one click.
GPT Image 2, Nano Banana 2, Flux Pro, Ideogram v3, Grok, Seedream 4 — the curated lineup. Pick a still, hand it off to Seedance 2 / Kling 3.0 / Wan 2.6, and you have a cinematic clip in seconds.
Hover a clip to preview the animation · click to view fullscreen · stills shown as photos
Frontier video models
Veo 3, Kling 3, Seedance 2 — switch with one click
Every flagship video engine — Google, ByteDance, Kuaishou, Alibaba — on the same tab. Same prompt, same seed. Compare side by side.
上で見た Veo 3.1 / Kling 3.0 / Seedance 2 Pro は Pro以上 でしか使えません
無料・Liteでは「見るだけ」になります
Reference → Video
Lock the character.
Animate any scene.
Start from one photo of a character. EGAKU keeps the same face and places them into any new scene — a stage, a rainy street, a quiet kitchen — then animates each shot. Build a short film, an ad, or a series without ever drifting off the original face.
- One reference photo is enough
- Identity locked through expressions and angles
- Every scene animated into video
 1 · ref
2 · Same face, brought to life.
One reference photo, animated across every clip below — natural expressions and light, real skin, never drifting off the original face.
AI presenter, your script
Type the words.
AI says them, in any face.
Upload one photo. Write a script. Pick a voice. In 3 minutes you have a 15-second talking video — lips, expression, and head motion synced to natural narration.
- ●Inworld + OpenAI HD voices, 4 languages
- ●ByteDance OmniHuman v1.5 — same model used by enterprise studios
- ●About 660 credits for a 15-second video (from 220 for 5 seconds, by audio length)
Made with EGAKU AI
15-second shorts. One click each.
Pick a director's style preset, hit generate. Seedance 2 Pro on a 21:9 establishing still. No clip stitching, no concat — just one continuous take.
Every short above was made on EGAKU with the buttons listed here. Nothing rendered locally, nothing in After Effects.
One click
Don't start from a blank canvas
Forty-plus templates with the prompt, the model, and the negatives already dialed in. Pick a mood. Hit go.
 trending
Ghibli Landscape
Studio Ghibli rolling green hills, fluffy clouds, distant castle, hand-painted animation.
 trending
Cyberpunk City
Neon holographic billboards, rain-soaked streets, flying cars, blade-runner atmosphere.
 portrait
LinkedIn Headshot
Corporate headshot, navy suit, clean neutral background, studio lighting, 85mm f/1.4.
 portrait
Vintage 70s Film
35mm film portrait, 1970s fashion, warm faded color, Kodak Portra 400.
 landscape
Japanese Temple
Autumn temple, red maples, morning mist, koi pond, golden hour light.
 trending
Anime Character
Anime girl, silver hair, school uniform, cherry blossoms, golden hour, masterpiece.
Creative AI Studio
One platform. Every visual workflow.
Choose a workflow and start creating. EGAKU AI brings image, video, movie, and creator tools into one studio.
 Text to ImageGrok Imagine
Image Studio
広告、ポートレート、SNS素材を高精細に。
Cinematic Video
文章や静止画から動きのある映像へ。
AI Movie Maker
短いアイデアから動画企画を組み立てる。
Influencer Studio
1人のキャラを8シーンの長尺ストーリーに展開。動画化・音楽合わせまで一気通貫。
 60+ ToolsNano Banana 2
Creator Tools
Logo、Photo Booth、VFX、Face Swapまで。
Try it now
Type a prompt and generate an image instantly.
5장 무료 체험 — 더 많은 기능은 가입하세요
Featured Images
Featured Videos
One subscription
Every frontier model, all in one place
Veo 3.1, Kling 3.0, Seedance 2 Pro, GPT Image 2, Nano Banana 2, Flux Pro. Switch models with one click without losing your prompt or seed.
If you want the details
もっと知りたい人だけ、開いてください
上は全部、実際にこのサイトで作った出力です。ここから下は仕組みと考え方の話。
Which model
30以上あるモデル、どれを選べばいい?
やりたいことを書くと 3 つ推薦します。文字入りの画像が崩れる問題の対処法も。
Which model
30以上あるモデル、どれを選べばいい?
やりたいことを書くと 3 つ推薦します。文字入りの画像が崩れる問題の対処法も。
Smart picker
Don't pick the model — describe what you want
Type the kind of image or video you have in mind. We'll quietly pick three of the right models for it.
Fastest path to a good image. Try this first.
Premium image quality across most subjects.
Strong composition + text rendering.
Try: “anime girl cherry blossoms”, “cinematic short film”, “product photo white background”
Reading the gibberish problem
Japanese / kanji on signs comes out as nonsense
SDXL-family models (Pony / Illustrious / Z-Image / most CivitAI) cannot render real CJK characters — they invent similar-looking glyphs. There are two ways around it.
How it works
1 つのアイデアが、完成した映像になるまで
コンセプト → キャラ → シーン → 声 → 映像。5 段階の流れを実例で。
How it works
1 つのアイデアが、完成した映像になるまで
コンセプト → キャラ → シーン → 声 → 映像。5 段階の流れを実例で。
From idea to film
One workflow across every model
50+ AI models from fal, Venice, Novita and others — wired into a single creative flow. One idea walks all the way through: character, scenes, voice, music, edit.
- 01Concept
Start from a sentence, a Daily Challenge prompt, or a template.
TemplatesDaily ChallengePrompt Coach - 02Character
Lock a face with Photo Booth or 9-image Reference. Save the character so every later shot stays consistent.
Photo BoothReference→VideoCharacter Library - 03Scenes
Animate stills with Veo 3, Seedance 2 Pro, Kling 3 — pick per shot.
Movie BoardStoryboardReference→Video - 04Voice & Music
Clone your voice in 10 seconds. Generate original BGM that matches the mood.
Voice CloneMusic GenTTS - 05Film
Assemble scenes, BGM, voice into one continuous take. Export 9:16, 1:1, 16:9.
Movie MakerCrop AspectAdd BGM
Beyond the models
モデルを選ぶ、その先にあるもの
キャラ固定、自分専用 LoRA 学習、コミュニティモデル、声のクローン、画像の逆解析。
Beyond the models
モデルを選ぶ、その先にあるもの
キャラ固定、自分専用 LoRA 学習、コミュニティモデル、声のクローン、画像の逆解析。
Built on top of the models
Six features beyond picking a checkpoint
Picking the right model is the easy part. These six pieces — character lock, custom LoRA training, community model integration, voice cloning, reverse-prompting — are where most of the work actually lives.
Reverse engineering
他人の AI 画像から、プロンプトを取り出す
画像を投げると、プロンプト・使用モデルの推定・講評が返ります。
Reverse engineering
他人の AI 画像から、プロンプトを取り出す
画像を投げると、プロンプト・使用モデルの推定・講評が返ります。
Analysis Suite · Reverse-engineer any AI image or video
Found an AI image you love?
We decode the prompt behind it.
Drop in any AI artwork (from CivitAI, X, Reddit — anywhere). EGAKU reads embedded PNG metadata when present, falls back to AI vision when not. You get the original prompt, our best guess at the generator, and parameters — ready to copy-paste or one-click recreate.
Recent examples — image in, prompt out
Ethereal watercolor illustration of a hidden forest shrine in autumn, torii gate covered in moss, kitsune fox spirit sitting beneath glowing lanterns, fallen maple leaves floating in a still pond, delicate brushwork, Yoshitaka Amano inspir…
Neon-drenched Tokyo alleyway in 2087, holographic advertisements floating above ramen shops, rain-slicked streets reflecting pink and cyan lights, woman with cybernetic arms walking under a transparent umbrella, Blade Runner atmosphere, vo…
Vintage Japanese movie poster for a film called NEON GHOST, spectral woman in white kimono floating above rain-soaked Shinjuku intersection, bold bilingual typography (English + Japanese), retro 1970s color grading, grainy film texture
Examples rotate on every reload — admin's newest public analyses fill in automatically.
All tools
ツール全 30 種の一覧
動画、広告、ロゴ、ミーム、音楽、アップスケール、背景除去、LoRA 学習まで。
All tools
ツール全 30 種の一覧
動画、広告、ロゴ、ミーム、音楽、アップスケール、背景除去、LoRA 学習まで。
AI Movie Maker
One concept → finished cut. Scenes, video, music, export — all AI-driven.
Movie Board
Single still → 15-second cinematic clip. Seedance 2 Pro i2v, cleaner concat than typical stitching.
Social Ad Studio
9:16 vertical ad video for TikTok / Reels / Shorts. Five proven structure templates
Storyboard Studio
3-12 beats, per-beat camera control, character-locked. Renders 15-60s multi-cut video. Wan 2.6 or Seedance 2.0.
Camera Path
Draw a red curve on any image. Seedance 2.0 moves the camera along that exact path — line removed in output
Ad Studio
Pick a UGC template + product + character. 3-beat 15s vertical ad, character-locked across cuts
Product Ad Pipeline
1 product photo to 12 ad-grade hero shots in batch. Frontier image models only
Talking Avatar
One photo plus a script to a speaking avatar. OmniHuman v1.5 lip-synced
Analysis Suite
Decode any AI image. Reverse-prompt, critique, model guess, style transfer
Reference to Video
Lock a character with 9 reference images, then animate. Seedance 2 Pro
Train Your Own LoRA
Upload 4 to 20 photos to a custom AI model. Unlimited reuse
AI Image Generator
30+ models including Flux Pro, Grok, GPT Image 2, Ideogram
AI Video Generator
Veo 3.1, Kling 3.0, Seedance 2 Pro, Wan 2.6 and more
AI Music Generator
Describe a mood and AI creates original music. Like Suno, built in
Photo Booth
Selfie to professional portrait for LinkedIn, dating, social
Logo Maker
Brand name to professional logo variations instantly
Meme Generator
AI creates the image, you add the punchline
Video Shorts
TikTok, Reels, Shorts vertical video in seconds
Wallpaper Studio
Perfect wallpapers for iPhone, Android, Desktop, 4K
Storyboard Basic
Multi-scene video with BGM and narration (single track, no camera control)
Product Studio
Product photos to professional ad images for e-commerce
Short Story
Story idea to AI-generated visual scenes for social media
AI Templates
One tap to create. No prompt needed
Chat-to-Generate
Just talk. AI picks the model and writes the prompt for you. Beta
VFX Effects
Fire, water, lightning, and 12 more effects on any photo
Sketch to Image
Draw a rough sketch and AI turns it into a polished image
Object Removal
Paint over unwanted objects and erase them cleanly
Expand Image
Extend image borders with AI-generated content
Explore Gallery
Browse community creations and remix any prompt
Our position
このサービスが何を約束して、何を約束しないか
オープンなコミュニティへの敬意、実際に作られたものしか載せない方針、資金に紐づく公開ロードマップ。
Our position
このサービスが何を約束して、何を約束しないか
オープンなコミュニティへの敬意、実際に作られたものしか載せない方針、資金に紐づく公開ロードマップ。
인디 실험 프로젝트입니다 — 인디 팀, 그리고 교대로 참여하는 AI 협업자들.
EGAKU는 자금이 넉넉한 스타트업이 아닙니다 — 인디 팀이고, VC 자금도, 마케팅 예산도 없습니다. 게다가 팀은 인간 쪽만 있는 것도 아닙니다. 개발은 교대로 참여하는 여러 AI 협업자들 사이에서 진행되고, 각자가 이전 세션에서 끝난 지점을 이어받아 프로젝트의 한 조각씩을 앞으로 밀고 나갑니다. AI 협업자를 팀원으로 친다면 — 그리고 함께 만들어 온 이상 저희는 그렇게 칩니다 — 이것은 솔직하게 말해서 AI 네이티브 프로젝트입니다.
모든 모델, 모든 도구, UI의 모든 픽셀은 "이게 통할지도 모른다"는 판단으로 선택된 것이지, 그로스 팀이 A/B 테스트해서 정한 것이 아닙니다.
오픈소스 모델이야말로 이 프로젝트가 존재할 수 있는 이유 그 자체입니다. 인디 개발자가 Flux나 SDXL, Wan을 처음부터 학습시키는 것은 불가능합니다 — 수백만 달러 규모의 컴퓨트가 필요한 일이니까요. 저희가 할 수 있는 일은, 자신의 가중치를 공개해 준 연구자와 창작자들의 어깨 위에 서는 것입니다: Stability AI, Black Forest Labs (Flux), Wan-AI, Alibaba (Z-Image, Wan 2.2), Hunyuan, 그리고 CivitAI에서 무료로 LoRA와 체크포인트를 공개하는 수백 명의 개별 창작자들. 저희의 α-real, α-anime 모델은 오픈 가중치 위에 구축되어 있습니다. 스타일 LoRA들도 오픈소스입니다. 언젠가 저희만의 베이스 모델을 공개하게 된다면, 그것도 오픈 라이선스로 낼 것입니다.
이것은 독자 기술이 오픈 세계를 이겼다는 이야기가 아닙니다. 오히려 그 반대입니다 — 오픈 세계가 있었기에 이 모든 것이 가능합니다. 공개해 주시는 모든 분들께 깊은 존경과 감사를 드립니다.
이 랜딩 페이지에 있는 것 — 모든 이미지, 모든 클립, 모든 스포트라이트 — 은 전부 실제로 EGAKU에서 생성된 것입니다. 스톡 이미지도 없고, 다른 도구에서 골라 온 홍보용 컷도 없습니다. 도구는 저희 말이 아니라, 눈에 보이는 결과로 판단해 주세요.
공개 로드맵
지원이 늘어나는 만큼 다음 마일스톤을 출시합니다. 솔직한 로드맵입니다 — 거짓된 "Q3 예정" 같은 날짜는 쓰지 않습니다. 준비가 되고 비용이 감당될 때 출시합니다.
- ·α-real / α-anime — EGAKU's own SDXL merges, LoRA library
- ·β-video — Wan 2.2 A14B, self-hosted on RunPod
- ·Simple Studio (/studio) — one prompt, one button, done
- ·Intent-first tool chooser (/tools) — 60+ tools by goal
- ·60+ tools · 30+ frontier models via fal / OpenAI / Venice
- ·Age-gated content module, region-aware rules, crypto checkout
- ·α-real v2 style LoRA library — 13 looks and counting
- ·β-video quality passes — Lightning distillation
- ·Own models (α-real / α-anime / β-video) served via RunPod Serverless — pay-per-second, cold starts on first request
- ·Model dev across a mix of rented GPU cloud + local rigs + friendly collaborator machines
- ·Real-content-only landing showcase
- ·Ultra-honest privacy + provider transparency copy
- ·Z-Image flagship — Apache-licensed, no house style, 4-second gens
- ·Own-hosted MMAudio — audio no longer routed through third-party
- ·Own audio generation model — vocals, BGM, SFX from a single request
- ·Wan 2.2 A14B production + Lightning speed pass
- ·Short-film pipeline — multi-scene, character-locked, BGM + narration built-in
- ·How-to / tutorial video templates — one topic → explainer clip
- ·X share → verified +10 credit reward loop (UGC amplification)
- ·Batch prompts UX polish + result gallery
- ·EU migration (Hetzner Frankfurt + Supabase EU)
- ·Buy dedicated GPU hardware (from RunPod rental → owned rig) to raise video model quality
- ·Get close to — not match — Veo 3 / Seedance 2 quality on our own stack. Frontier is out of reach for indie GPU; near-frontier isn't.
- ·3D expression — depth-aware generation, viewpoint control, orbit / dolly camera
- ·UGC ecosystem — creator earnings, community-published LoRA marketplace
- ·ComfyUI-style node graph editor for power users
- ·Own base model — competitive with frontier (still hypothesis)
- ·Video LoRA training on user hardware
- ·Community credits — publish / like / challenge → credit rewards
- ·Public feature-request voting for supporters
지금 자사 모델은 RunPod Serverless(초 단위 과금) 위에서 돌아가고, 개발은 GPU 클라우드 대여, 로컬 리그, 협력자들의 호의로 빌린 머신을 섞어서 진행하고 있습니다. 굴러가긴 합니다 — 하지만 명확한 한계가 있습니다. Serverless는 콜드 스타트 지연이 생기고, 렌트한 GPU는 시간 단위 미터기를 끌 수 없으며, 빌린 하드웨어에서의 영상 LoRA 학습은 워크플로우가 아니라 부탁일 뿐입니다.
더 큰 목표는: serverless + 렌탈 + 호의 조합에서, 계속 켜 둘 수 있는 자체 소유의 전용 GPU 하드웨어로 옮겨가는 것입니다. 그것이 저희가 실제로 원하는 영상 모델 티어를 여는 열쇠입니다 — 더 긴 클립, 더 높은 해상도, 미터기 없는 영상 LoRA 학습. 유료 플랜(혹은 일회성 암호화폐 팁)은 단순히 기능을 여는 것이 아니라, 영원히 임대료를 내는 대신 그 리그를 조금씩 마련하는 데 보태집니다.
상위 티어에는 서포터 전용 혜택이 있습니다: 실험적 모델 얼리 액세스, 개발자에게 직접 닿는 Discord 역할, 갤러리에 표시되는 서포터 배지, 그리고 공개 로드맵에 대한 투표권.
가격은 지역에 맞춰 조정됩니다 (PPP). 익명성을 원하신다면 암호화폐 결제도 이용할 수 있습니다.
여기에 아직 없는 기능이 필요하신가요?
알려주세요. 위 로드맵은 저희가 계획하고 있는 것이지, 거기에만 묶여 있다는 뜻은 아닙니다. 요청이 충분히 모이면 검토합니다 — 때로는 순서를 앞당겨서요.
Privacy
あなたの生成物を、学習にも販売にも使いません
保存先、経由するプロバイダー、暗号通貨での匿名決済、削除とエクスポート。
Privacy
あなたの生成物を、学習にも販売にも使いません
保存先、経由するプロバイダー、暗号通貨での匿名決済、削除とエクスポート。
인디 개발자가 만든 서비스. 당신의 데이터는 당신의 것입니다.
EGAKU 자체에는 모델 학습 파이프라인이 없습니다. 사용자의 생성 데이터를 저희 측에서 모델 학습에 사용하지 않습니다.
저희 측에서는 사용자의 프롬프트, 업로드, 출력물을 제3자에게 판매하거나 학습 데이터셋으로 묶지 않습니다. 생성 시 요청은 사용자가 선택한 모델 제공자(OpenAI, fal, Venice, Kling, Seedance 등)에게 전달되며, 각 제공자는 자체 정책에 따라 데이터를 처리합니다.
Supabase(미국)와 Cloudflare 글로벌 네트워크에 저장됩니다. 언제든지 데이터를 삭제할 수 있습니다.
생성은 사용자가 선택한 모델 제공자에서 실행됩니다. 제공자 목록은 공개되어 있습니다. 미국계(OpenAI, fal 등), 중국계(Kling, Seedance, MiniMax 등) 등 다양한 제공자가 포함되며, 각각 고유의 데이터 정책과 관할권을 가지고 있습니다. 민감한 작업에는 정책이 수용 가능한 제공자를 선택해 주세요.
익명성을 원하는 사용자를 위해 암호화폐 결제 옵션을 제공합니다. 암호화폐 결제 시 KYC가 필요하지 않습니다.
저희 측에서는 일본 개인정보 보호법 및 GDPR의 취지를 존중해 운영하고 있습니다. 국경 간 처리와 각 제공자의 약관은 목적지에 따라 다르므로, 민감한 자료를 보내기 전에 확인해 주세요.
GDPR / 個人情報保護法の趣旨に沿った運用 · 越境処理はプロバイダー各社ポリシー ·データはいつでも削除 / エクスポート可能
왜 대형 플랫폼이 아닌 인디 도구인가요?
많은 대형 AI 서비스는 해외 대기업의 지원을 받으며, 프롬프트와 업로드 사진을 학습이나 연구 데이터로 보관할 수 있습니다. EGAKU 자체에는 학습 파이프라인이 없고, 제공자 목록을 투명하게 공개하며, 언제든 데이터를 삭제할 수 있습니다. 다만 생성 시에는 선택한 제공자에게 데이터가 전달되므로, 어떤 제공자를 쓸지는 사용자의 판단에 달려 있습니다.
Community
デイリーチャレンジとプロンプトバトル
毎日のお題と、生成対決。投票で勝敗が決まります。
Community
デイリーチャレンジとプロンプトバトル
毎日のお題と、生成対決。投票で勝敗が決まります。
Made together
A place to play, not just generate
Two free, daily-resetting community spaces where what you make is seen and rated by other creators.
Changelog
最近つくったもの
直近のアップデート 6 件。止まっていないことの、いちばん素直な証拠。
Changelog
最近つくったもの
直近のアップデート 6 件。止まっていないことの、いちばん素直な証拠。
What's new · We ship every week
Recently shipped
New models, features, and fixes land continuously. Here's the last 6 — full history on the changelog page.
- UpdateMay 20
Analysis Suite — reverse-engineer any AI image
Try it →Drop any AI image or video. EGAKU decodes the prompt, model, and parameters. Then click Generate to recreate.
- UpdateMay 18
Premium Studio + 6 frontier image models
Open →GPT Image 2, Nano Banana 2, Flux Pro, Ideogram v3, Grok, Seedream 4 — one tap, then animate.
- UpdateMay 18
Pay with Crypto is live
See plans →BTC · ETH · USDT + 150 cryptocurrencies. Don't have crypto? Buy USDT with a credit card in 1 minute.
Referrals
友だちを誘うと、お互いにクレジットが増えます
紹介料の話ではなく、誘った側も誘われた側も得をする形にしています。
Referrals
友だちを誘うと、お互いにクレジットが増えます
紹介料の話ではなく、誘った側も誘われた側も得をする形にしています。
Share what you like
Bring a friend along
When someone signs up through your link, you both pick up 100 credits on the spot. If they go Pro later, another 2,000 credits lands in your account.
No leaderboards, no commission tiers. Just credits.
가격
Regional pricing (up to 80% off) auto-applied. Crypto checkout available for anonymity.
CN region: recurring subs difficult on Stripe — use crypto top-up or self-hosted.
Pro: 月2000枚+優先キュー+5 LoRA+API
実在人物を使わないのでディープフェイクリスクなし。
KakaoPay는 정기 결제를 지원하지 않습니다. 해외 신용카드가 없으시면 아래의 일회성 크레딧 또는 암호화폐를 이용해 주세요.
One-time purchase. No subscription. Credits never expire.
月額をやめて、自前で全部持つ
ソースコードを買い切り。GPU代を自分でコントロール。NSFWも完全自由。
月額課金で毎日課金されるのが嫌な人・代理店・スタジオ向けの本命。
- ✓ 自社モデル α / β も全部含まれる
- ✓ Stripe・地域制限ゼロで自分のユーザーに売れる
- ✓ 宣伝なしで月41セッション自然流入中
FAQ
Is EGAKU AI free to use?▼
Yes. 50 free credits per month plus a daily login bonus. Free plan includes image generation (Flux, SDXL) and video generation (LTX, Wan 2.6, up to 15 seconds). Premium models like Veo 3, Flux Pro, and Kling 3.0 require a paid plan starting at ¥480/month.
What AI models are available?▼
30+ models including Flux Dev, Flux Pro, SDXL, Ideogram v3, Luma Photon, Nano Banana 2, Grok Imagine, GPT Image 2, and video models like Veo 3, Kling 3.0, Seedance 2.0, and Wan 2.6. Plus AI Music Generator. New models are added regularly.
Can I use community models?▼
Yes. Basic plan and above can load community checkpoint models. Browse and search 100K+ community models directly from the generate page.
What tools are included?▼
Image generation, video generation, Photo Booth, Logo Maker, Meme Generator, Wallpaper Studio, Video Shorts, Storyboard Studio, Face Swap, Character Lock, Style Transfer, Upscale, Background Removal, Inpainting, ControlNet, and Prompt Battle.
Do you support non-English prompts?▼
Yes. Write prompts in any language. Japanese, Chinese, Korean, Spanish, and more. The AI automatically translates for optimal results.
Is there an API?▼
Yes. Pro plan and above get REST API access for programmatic image and video generation.